

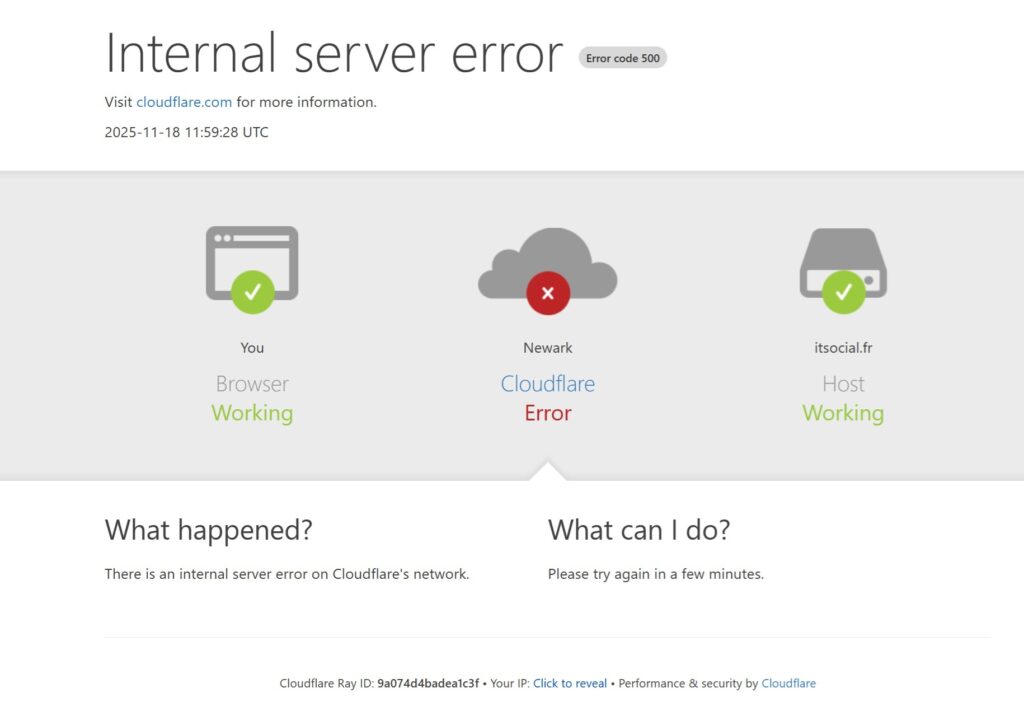
Major Cloudflare Outage Disrupts Access to Thousands of Websites Worldwide
On November 18, a significant outage struck Cloudflare, causing widespread disruptions to thousands of websites globally. While the issue, linked to a deployment incident across multiple data centers, was resolved in under an hour, it once again raises concerns about the robustness of critical high-availability infrastructures.
Cloudflare has become a cornerstone of global web performance, providing content distribution, security, and traffic optimization for millions of sites. However, a simple configuration error led to notable disruptions across Internet traffic. The incident unfolded shortly after 11 AM Paris time, impacting a diverse range of services, including news portals, ticketing sites, and development platforms—demonstrating the widespread dependence on Content Delivery Networks (CDNs).
As a key player in the global Internet infrastructure, Cloudflare operates a distributed network across over 300 cities worldwide, providing critical functions such as content distribution, rapid DNS resolution, protection against DDoS attacks, application firewalls, and HTTP exchange acceleration. Many essential websites, including institutional and financial pages, rely on Cloudflare for consistent uptime and minimal latency, making it an invisible yet vital link in the user’s Internet experience.
Human Error During Scheduled Deployment
In a detailed blog post, Cloudflare explained that the outage stemmed from human error during a planned deployment that affected a subset of its data centers in North America, Europe, and Asia. Specifically, the propagation of an update to the “Tiered Cache” component resulted in configuration file discrepancies, preventing affected nodes from processing incoming requests accurately. This misconfiguration led to a widespread failure rate, with numerous 500 error responses across a significant portion of global traffic.
The issue was quickly identified by internal alert systems, prompting Cloudflare to initiate a rollback to the previous functioning version of the faulty component. By 11:50 AM, nearly all services had returned to normal. Importantly, no data compromises or malicious attacks were detected; the event was solely linked to a routine maintenance operation that went awry. The company has committed to enhancing its internal safeguards, particularly regarding cross-validation in multi-site deployments.
A 45-Minute Outage with Exponential Impact
While the downtime lasted no more than 45 minutes at its peak, the effects were amplified by the very architecture of the modern Internet. Used as a WAF, content accelerator, and DNS network by many clients—including in the public and financial sectors—Cloudflare handles a substantial portion of web traffic. Numerous companies reliant on its services without active redundancy saw their sites become inaccessible, often without options for redirecting traffic.
Analysts highlight the recurring nature of such seemingly minor incidents, which reveal the underlying fragility of the digital economy when it relies on centralized infrastructures. Following significant outages at Microsoft 365 in September 2025 and AWS in October 2025, Cloudflare’s brief disruption adds to a series of events that illuminate the risks facing global web service chains. The focus is shifting from performance to resilience.
Towards a Distributed and Monitored Architecture
The lessons learned from this incident resonate with many IT leaders: redundancy, version control, compartmentalization of deployment zones, and rollback testing are becoming operational priorities. In a resilient architectural model, every critical component—from DNS to CDN and WAF—must be easily replicated or isolated without impacting overall service.
Moving forward, many companies are reevaluating their implicit dependence on a single provider, even for components previously considered non-critical. In response, Cloudflare has pledged to release a comprehensive post-mortem report detailing its deployment system improvements. The company already claims to be pursuing initiatives aimed at progressively decoupling updates by region and enhancing isolation mechanisms. It remains to be seen whether these technical promises will resonate with clients, who are increasingly outsourcing without fully mapping out their digital dependencies.



