

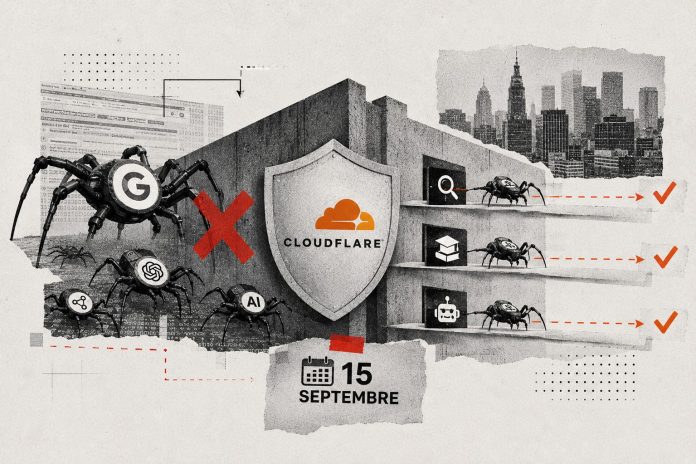
Starting September 15, Cloudflare will enforce a categorization of web crawlers based on their intended purpose, differentiating between research, model training, and agentic action. By default, training and agent activity will be blocked on ad-supported pages. Mixed-use indexers that refuse to specify their aims will also be denied access to those pages. Cloudflare, which handles a substantial portion of global internet traffic, is positioning itself as a gatekeeper for AI access to web content.
From September 15, all indexers, AI access points, and search functions will need to be properly identified. Each bot must declare its purpose and verify its identity through Web Bot Auth, the open bot authentication framework launched by Cloudflare last year. At the same time, new customers, new sites of existing clients, and free accounts that haven’t been configured will automatically switch to the new default setting: research allowed, with training and agent activities blocked on ad-supported pages. The next two months will be used to consult with the ecosystem and finalize these classifications.
This shift extends a trend that began a year ago when Cloudflare made blocking training a default option and initiated its AI bot control. Since then, over half of web requests originate from automated systems, and more than fifty content licensing agreements have been established between publishers and AI platforms. The primary target of this new initiative is unnamed but implicitly points to a leading search engine that possesses approximately twice as much information as major AI companies, according to Cloudflare, because its unique crawler links indexing to model training. “As the majority of internet traffic is no longer human-driven, we must accelerate efforts to foster a sustainable ecosystem,” stated Matthew Prince, co-founder and CEO of Cloudflare.
Consultative robots.txt gives way to network blocking
This change represents a significant paradigm shift. The robots.txt file expressed a preference that crawlers could freely disregard, whereas Cloudflare’s classification operates at the network level, before requests even reach a website. Clients retain control, with every setting adjustable from their dashboard; however, the default will set the norm—given that most sites never modify their default settings.
The system also implements a separation that regulators have yet to mandate—distinguishing between search, which drives traffic to publishers, and AI usage that captures it. A mixed-use indexer will need to choose to either split its purposes or lose access to monetized pages on protected sites. The pressure primarily targets engines that base their AI responses on their historical search crawlers, forcing publishers to contend with both aspects.
A content marketplace takes shape
This classification brings with it a commercial layer. The Attribution Business Insights dashboard displays which bots consume a company’s content and quantifies the human traffic each AI company returns, creating a previously unseen asymmetry of information in all licensing negotiations. In the same breath, Cloudflare is pushing a discipline it refers to as Answer Engine Optimization (AEO), which measures a content’s presence in generated responses, akin to how audience analysis supported the search era.
Monetization completes the structure. The Pay Per Crawl model, which billed for data collection, has transitioned to Pay Per Use, compensating publishers when their content appears in actual responses. Ceramic.ai will pay for each mention in its results, providing queries and rankings in return, while You.com will enable agents to purchase premium content on-demand. These negotiated agreements benefit major publishers but do not scale to the broader web, targeting precisely this long tail of automated content markets. Cloudflare also posits an efficiency argument, noting that more than half of the traffic generated by AI crawlers revisits unchanged pages—waste that the network’s freshness signals aim to eliminate.
A private arbiter, both judge and stakeholder
By combining bot identities, usage metrics, and payment rails, Cloudflare positions itself as a tollbooth operator in the emerging agentic economy, including the nascent agent commerce where purchasing agents will need authentication to transact. The defaults it chooses are set to become the de facto standards for millions of sites, creating a normative power exercised by a private American company, the implications of which extend even to European content.
For organizations, the September 15 deadline transforms a mere security setting into a governance decision. The policy governing bot access to their sites—ensuring they remain discoverable by agents and response engines without relinquishing intellectual property—now involves IT, marketing, and legal teams. Conversely, the agents deployed by companies will need to specify their identity and purpose, and in the future, pay for the content they consume—an added cost of data freshness that must be factored into the economic equation of their projects, which introduces a new dependency on the toll operator.
Thus, the regulation of AI access to the web is currently being shaped in the dashboards of an infrastructure provider, not through legislation. The September 15 deadline will reveal whether mixed-use indexers comply with this separation or circumvent Cloudflare’s network, while European publishers—the stated primary beneficiaries—will gauge the cost of entrusting content arbitration to a private tollbooth.



