A study published in late 2025 reveals a troubling insight. Both humans and small transformers adjust their learning based on the diversity of examples they receive. The more repetitive the data, the more memory dominates. Conversely, the more varied the data, the more reasoning takes precedence.
With 530 Volunteers and the Same Tests, Research Shows When Memory and Rules Prevail
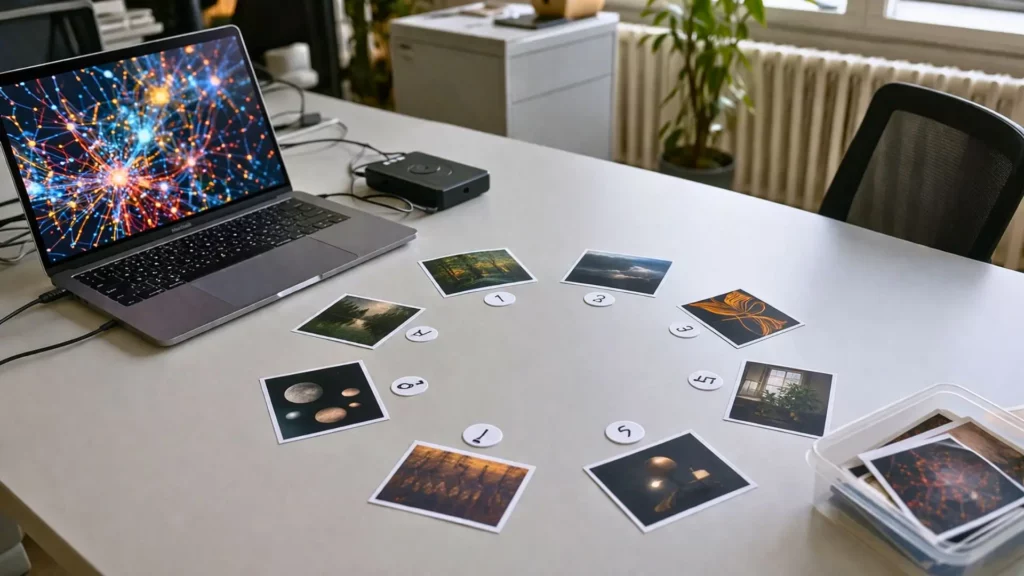
The researchers compared 530 volunteers with small neural networks on the same task. Each participant was tasked with linking images to numbers. The team then altered the frequency of examples. This adjustment led to similar learning choices emerging.
When training predominantly presented repeated cases, both humans and models tended to remember direct associations more. In contrast, varied series encouraged the application of a rule. The tipping point appears around α = 1. This is the key finding.
A Single Task and Two Reflexes, as Example Variety Shapes Memory and Reasoning in All
Specifically, the study contrasts two reflexes. The first stores a response as a learned fact, while the second identifies a rule and applies it in different contexts. In psychology, this aligns with acquired memory versus reasoning. In AI, it is referred to as in-context learning and in-weight learning.
This can be illustrated with multiplication. For 2 × 4, you often retrieve a memorized answer. For 6 × 13, you apply a method. However, the study indicates that both pathways heavily depend on the types of initial examples viewed, not just the task itself.
When Repetition and Novelty Coexist, Humans and Models Combine Two Strategies and Follow the Same Path
The most intriguing findings arise when data mixes repetition with novelty. In such cases, humans and models more frequently become dual learners. They retain useful associations while also being able to infer a rule when a new example appears.
The researchers didn’t only evaluate final scores; they tracked mouse movements in humans alongside the attention of the models. Both systems seem to employ a two-step mechanism to address scenarios utilizing a rule.
First, the participant or model identifies the target image within the circle. Then, they look for the correct answer three positions away. This parallel remains striking. However, the authors emphasize a crucial point: this research is based on small transformers and a deliberately simplified task.
When Diversity Comes First, Humans Retain the Rule While Small Models Quickly Deteriorate
This is where the gap becomes evident. When training begins with varied examples, humans tend to retain the rule better afterwards, then add the memorization of repeated cases. Conversely, small transformers more easily lose their initial strategy. The authors refer to this as catastrophic interference.
In other words, the order of examples matters just as much as their content. If you learn first through variety, you maintain a certain flexibility. In contrast, heavy redundancy from the outset may cause you to become quickly locked into rote memorization. This highlights a practical approach to considering the order of examples.
However, one should not rush to a hasty educational conclusion. The experiment remains very controlled and does not assess a classroom or a large language model. Ultimately, it raises a significant question: can we train more flexible AIs by better organizing data from the outset?